The blog.
15 posts on claude, page 1 of 2RSS feed
Is Ponytail 5 Worth It? I Tested It Across 700 Claude Code Sessions
Ponytail 5 claims it makes Claude write half the code, 26% cheaper and 41% faster. I ran the benchmarks across 700+ Claude Code sessions. The numbers hold up — but whether you should install it depends entirely on how you prompt.
Haiku 5.5 vs GPT-6 Luna: The Benchmarks Lied
Anthropic's benchmarks said Haiku 5.5 crushes OpenAI's GPT-6 Luna. I ran them head-to-head on the same prompts and harness — and the real-world results told a completely different story.
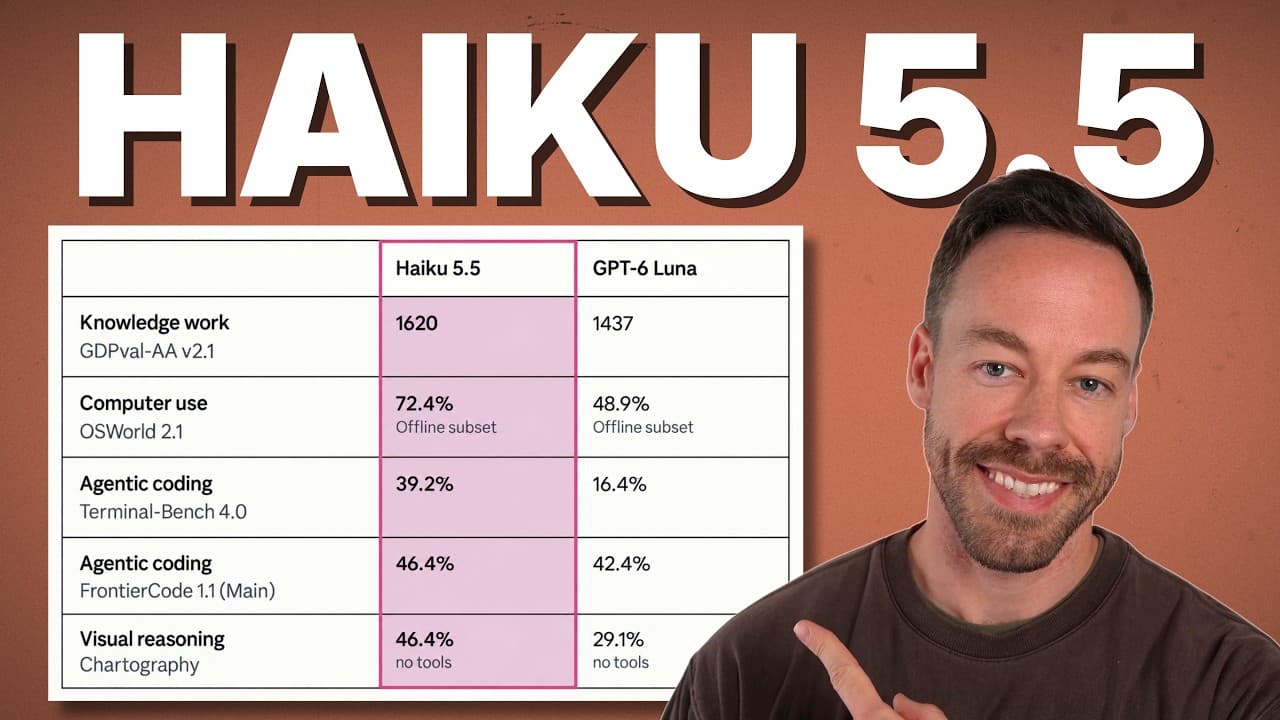
Claude Haiku 5.5: The Cheap, Fast Model Anthropic Was Missing
Claude Haiku 5.5 is roughly 75% cheaper than Haiku 4.5 and finally gives Anthropic a small, fast model that competes with OpenAI's cheap tier. Here's what the benchmarks, effort levels, and pricing actually mean for you.
You're Using Jev Wrong: 5 Mistakes to Fix
Jev is a classifier, not a chatbot — 200x faster and 400x cheaper than top LLMs. Here are the 5 mistakes most people make with Jev and how to fix each one.
Sonnet 5.5 vs Opus 5.5 vs GPT-6 Astra: I Tested All Three
I ran Claude Sonnet 5.5, Opus 5.5, and GPT-6 Astra through four real-world builds. Opus won overall, but the gaps were smaller than the benchmarks suggest.
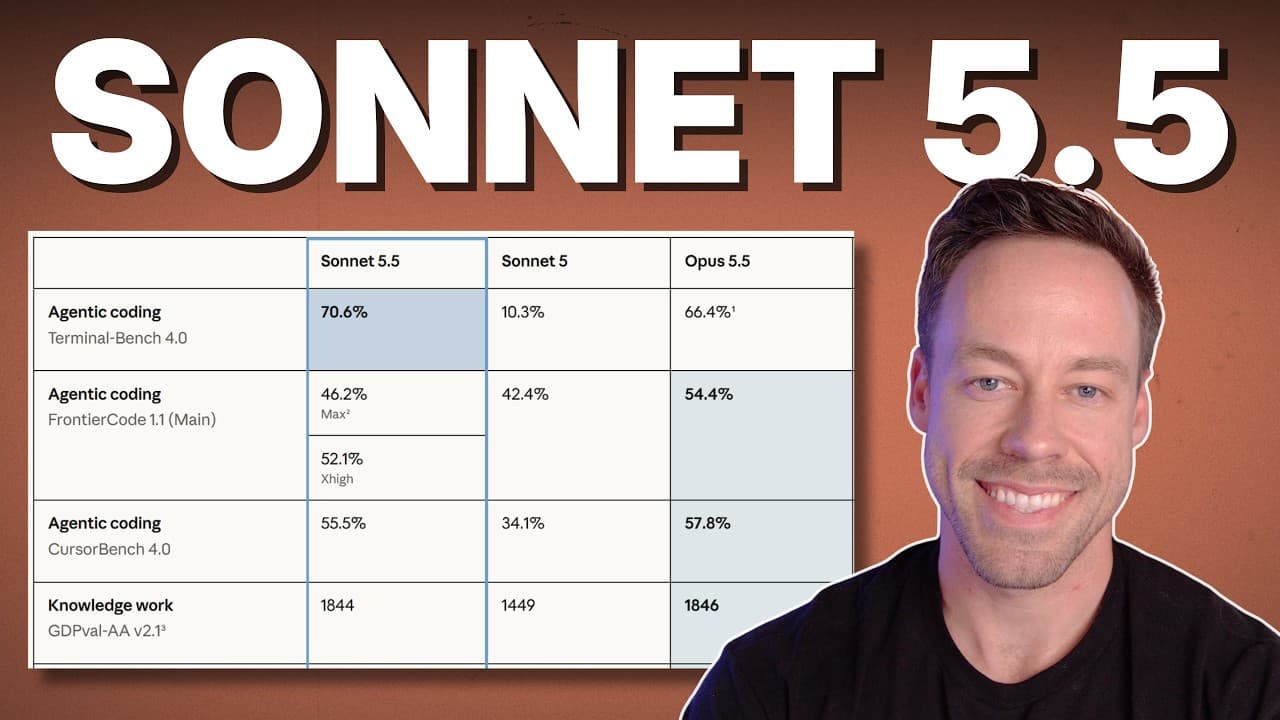
Claude Sonnet 5.5: Beats Opus at Coding, Half the Cost
Claude Sonnet 5.5 is 30% faster, 30% cheaper, and on one agentic coding benchmark it actually edges out Opus 5.5. Here's what the numbers mean for your day-to-day work.
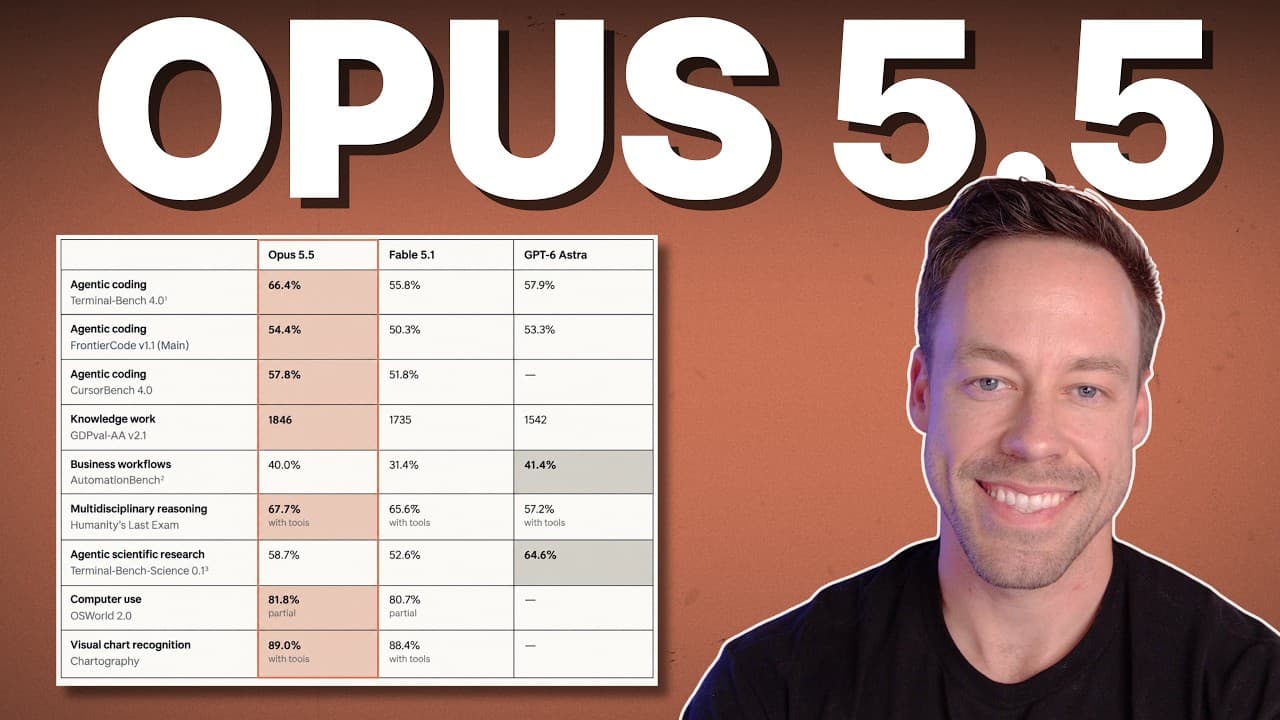
Claude Opus 5.5: Fable 5.1 Performance at 40% Less
Claude Opus 5.5 matches Fable 5.1 performance at about 40% less cost. Here are the benchmarks, per-task pricing, and which effort level to actually use.
Fable 5.1 Watermarks: How AI Text Watermarking Actually Works
Fable 5.1 is the first Anthropic model to watermark everything it writes. Here's how the watermark actually works and the only real way to get around it.
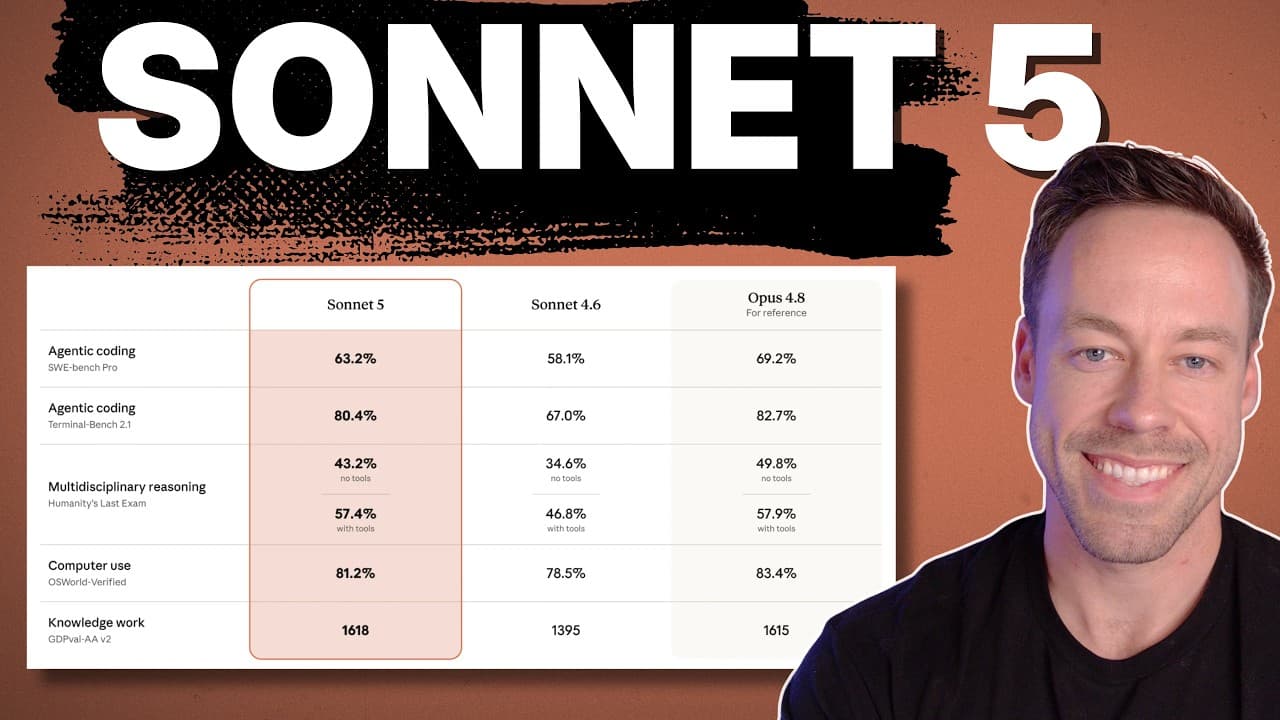
Sonnet 5 vs Opus 4.8: Which Model Should You Use?
Anthropic's Sonnet 5 lands within a few percentage points of Opus 4.8 at less than half the cost. Here's the pricing, the benchmarks, and the real decision — when Sonnet 5 wins and when Opus is still cheaper.
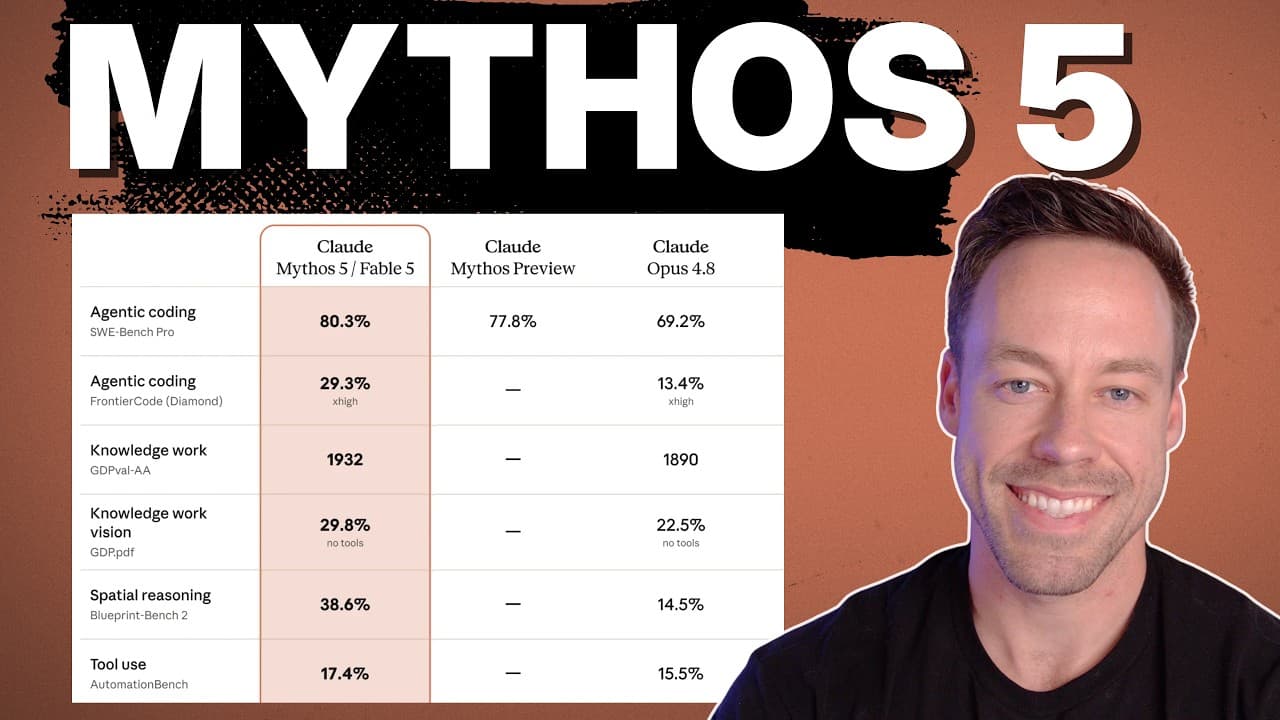
Claude Fable 5 and Mythos 5: What Actually Changed
Anthropic just shipped Claude Fable 5 to everyone and Mythos 5 to a select few. Here's the real breakdown: the benchmarks, the $10/$50 pricing, the safeguards, and whether Fable is just nerfed Mythos.
Claude Opus 4.7 Benchmarks: What Actually Changed in 2026
Anthropic just dropped Claude Opus 4.7. The benchmarks show a real jump in coding, vision, and document reasoning. Here's what matters and what it costs.
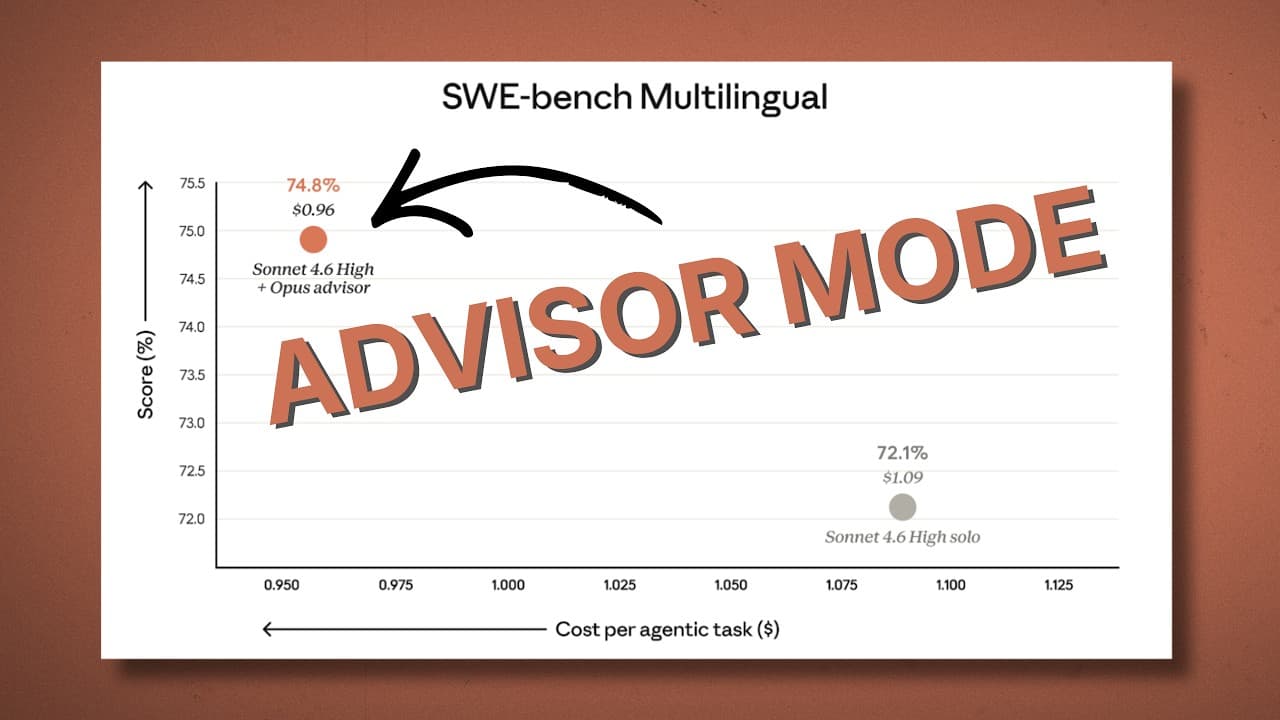
Claude's New Advisor Mode: Better Results + Cheaper
Anthropic's new Advisor Mode pairs Opus as a planner with Sonnet or Haiku as executor — beating standalone Sonnet on benchmarks at a fraction of the cost.