The blog.
15 posts on ai-models, page 1 of 2RSS feed
Haiku 5.5 vs GPT-6 Luna: The Benchmarks Lied
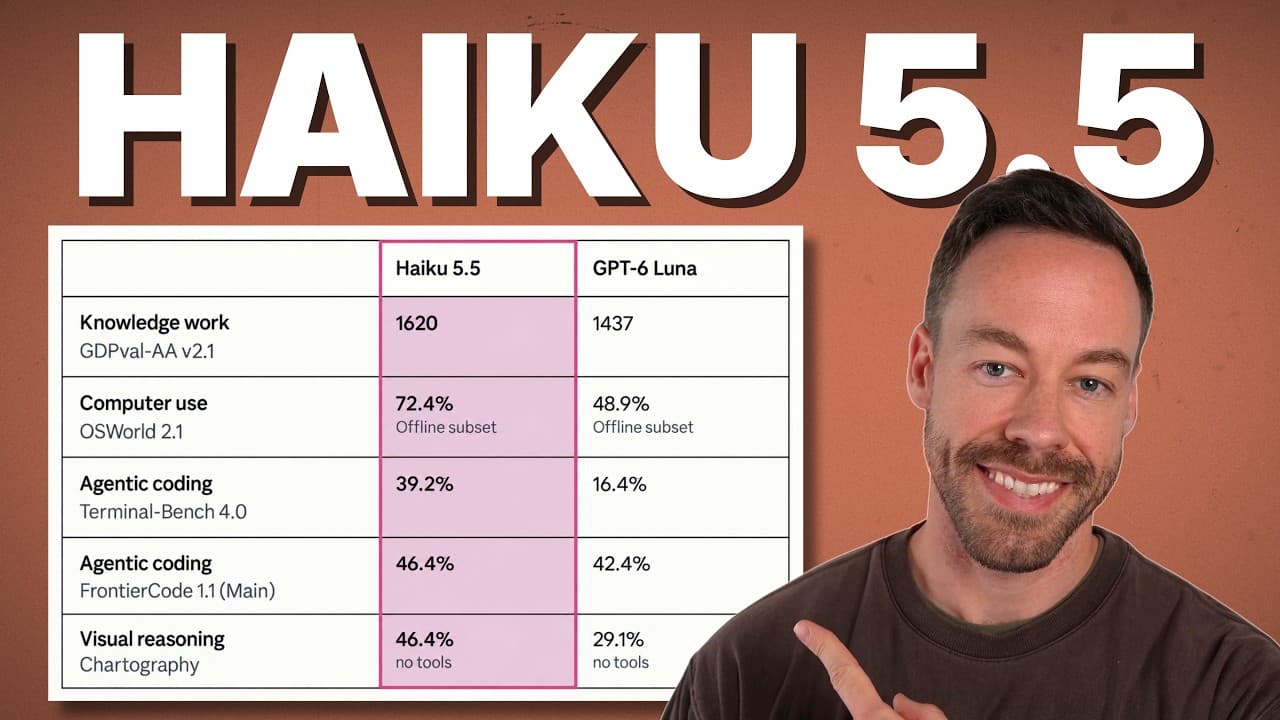
Anthropic's benchmarks said Haiku 5.5 crushes OpenAI's GPT-6 Luna. I ran them head-to-head on the same prompts and harness — and the real-world results told a completely different story.
Claude Haiku 5.5: The Cheap, Fast Model Anthropic Was Missing
Claude Haiku 5.5 is roughly 75% cheaper than Haiku 4.5 and finally gives Anthropic a small, fast model that competes with OpenAI's cheap tier. Here's what the benchmarks, effort levels, and pricing actually mean for you.
You're Using Jev Wrong: 5 Mistakes to Fix
Jev is a classifier, not a chatbot — 200x faster and 400x cheaper than top LLMs. Here are the 5 mistakes most people make with Jev and how to fix each one.
GPT-6.1 Sol vs Sonnet 5.5: Which One Actually Wins?
OpenAI's GPT-6.1 Sol posts insane benchmarks at a fraction of the cost. I ran it head-to-head against Sonnet 5.5 across four real builds to see if the numbers hold up.
Sonnet 5.5 vs Opus 5.5 vs GPT-6 Astra: I Tested All Three
I ran Claude Sonnet 5.5, Opus 5.5, and GPT-6 Astra through four real-world builds. Opus won overall, but the gaps were smaller than the benchmarks suggest.
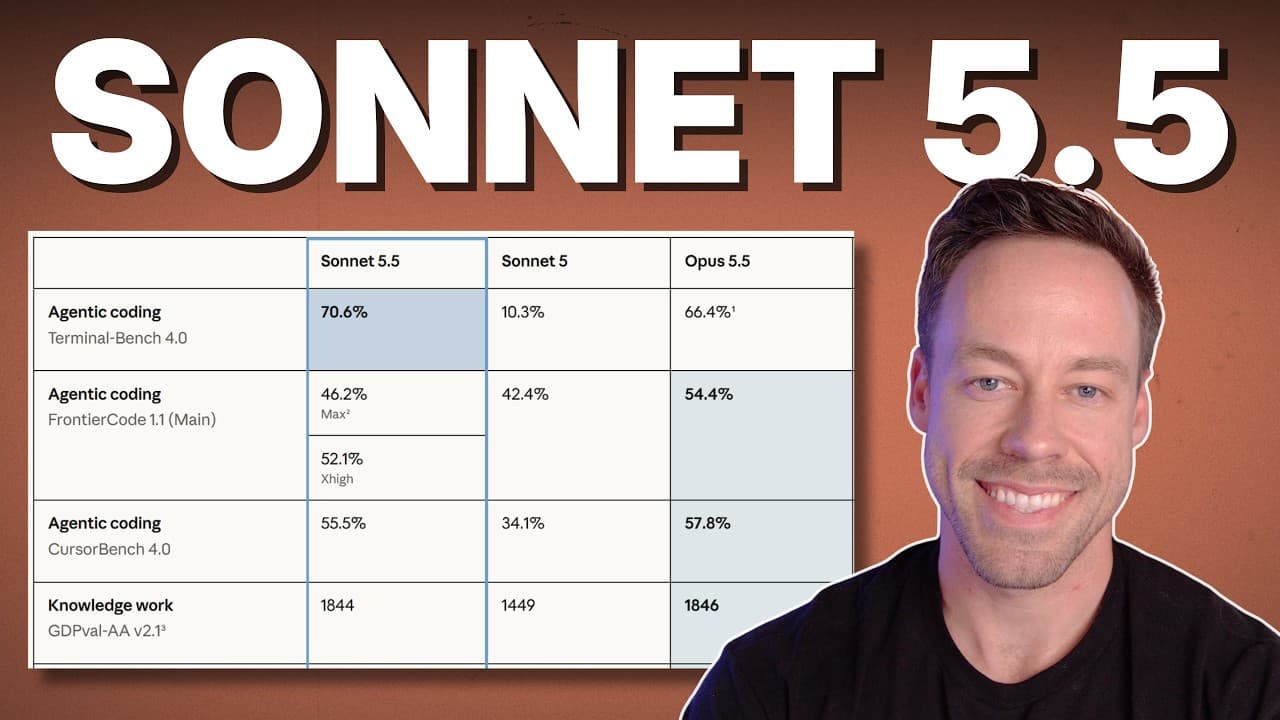
Claude Sonnet 5.5: Beats Opus at Coding, Half the Cost
Claude Sonnet 5.5 is 30% faster, 30% cheaper, and on one agentic coding benchmark it actually edges out Opus 5.5. Here's what the numbers mean for your day-to-day work.
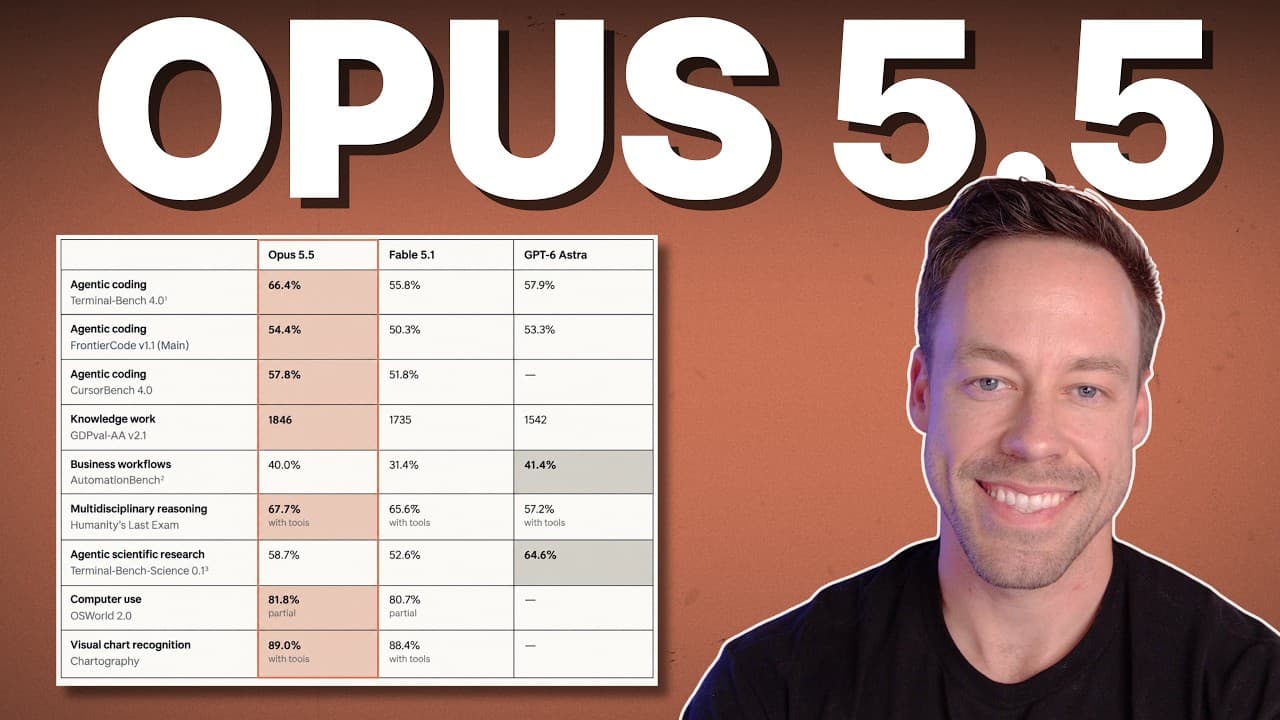
Claude Opus 5.5: Fable 5.1 Performance at 40% Less
Claude Opus 5.5 matches Fable 5.1 performance at about 40% less cost. Here are the benchmarks, per-task pricing, and which effort level to actually use.
GPT-6 Soul & Luna: Cheaper Models That Still Deliver
OpenAI's GPT-6 Soul and Luna trade a few benchmark points for massive cost savings. Here's what the numbers actually say and when to reach for each one.
Union Alpha: I Tested the Free Stealth AI Model
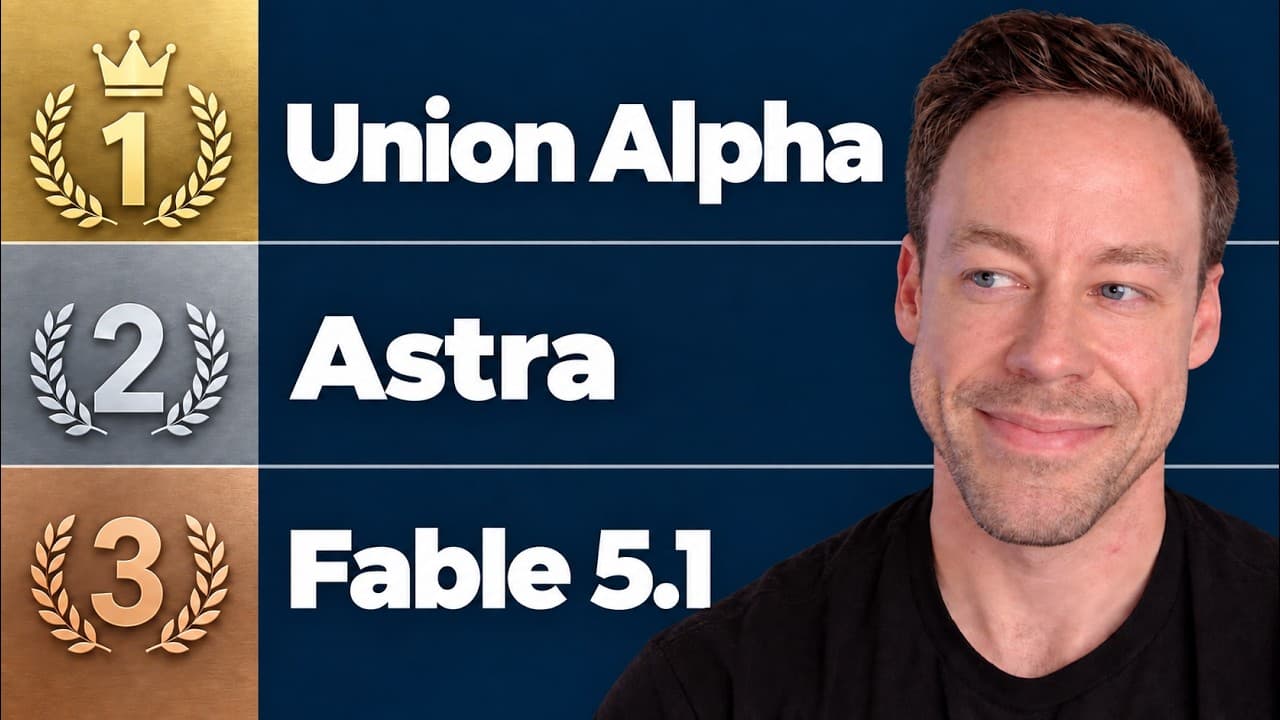
Union Alpha is a free stealth AI model on OpenRouter with a 262K context window. I tested it head-to-head against Opus 5, Fable, and Astra.
GPT 6 Astra vs Claude Fable 5.1: Real Tests
I ran GPT 6 Astra and Claude Fable 5.1 head-to-head on four real builds — a Fortnite clone, a landing page, motion graphics, and a 3D globe dashboard. Here's who actually won, and why the benchmarks only tell half the story.
Fable 5.1: Better Benchmarks, 25% Lower Cost
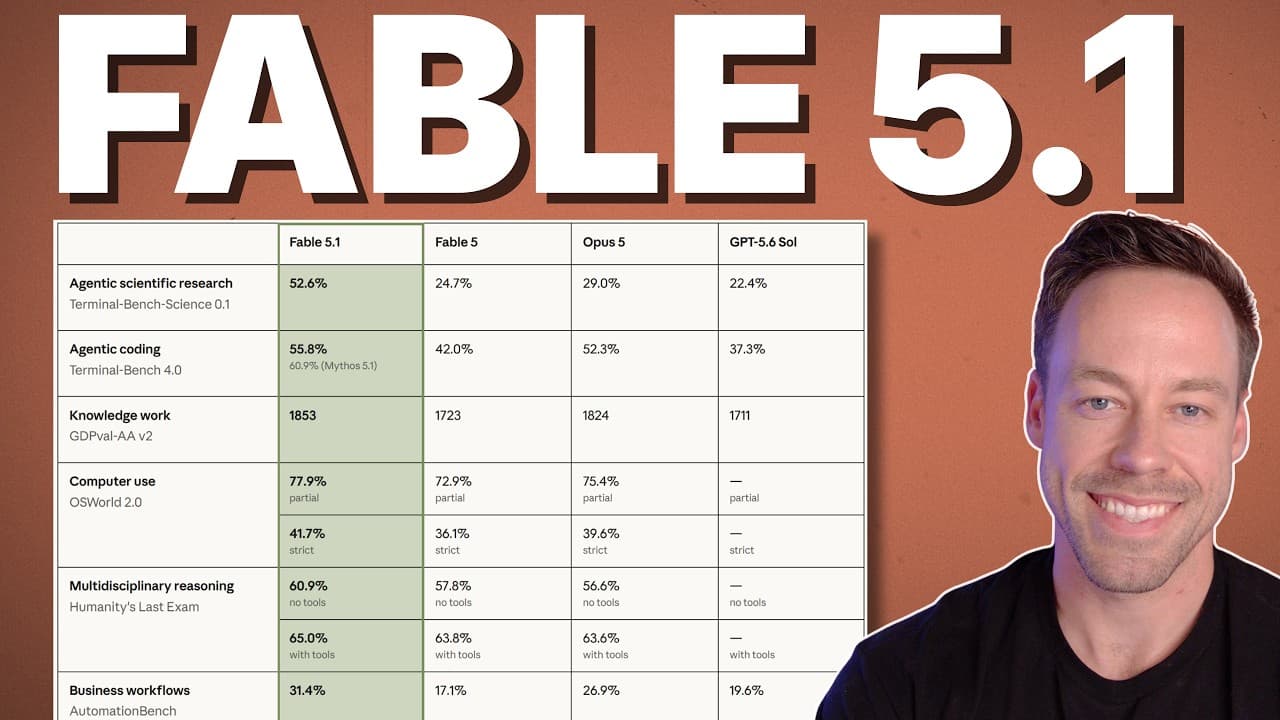
Fable 5.1 beats Fable 5, Opus 5, and GPT 5.6 Soul across the board while costing an estimated 25% less — up to 45% less on long-running agentic work. Here's everything that actually changed.
Claude Opus 5 Benchmarks: Fable 5 Performance at Half the Cost
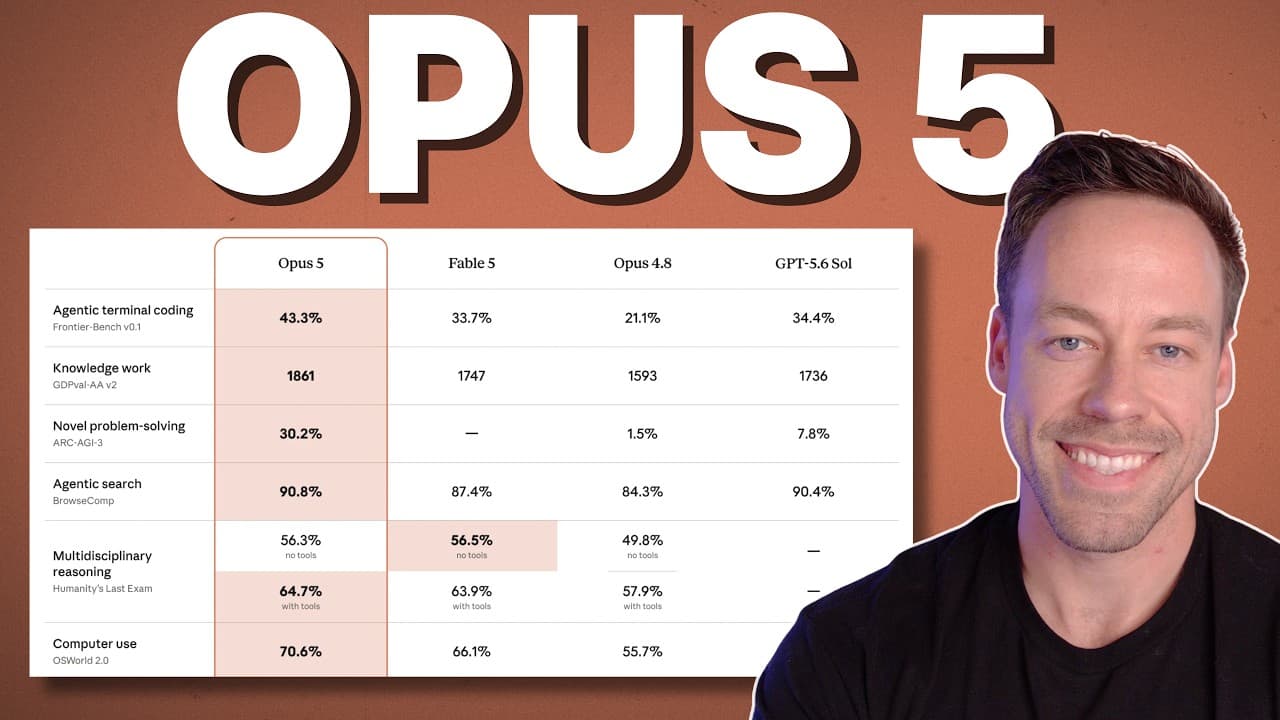
Claude Opus 5 matches Fable 5 on most benchmarks at half the cost, plus a massive jump over Opus 4.8. Here is what actually matters in the release.